
🔊 Listen to this article

Unpacking the Unexpected Consequences of a ChatGPT Showdown Perplexity
🛠️ Why is this happening
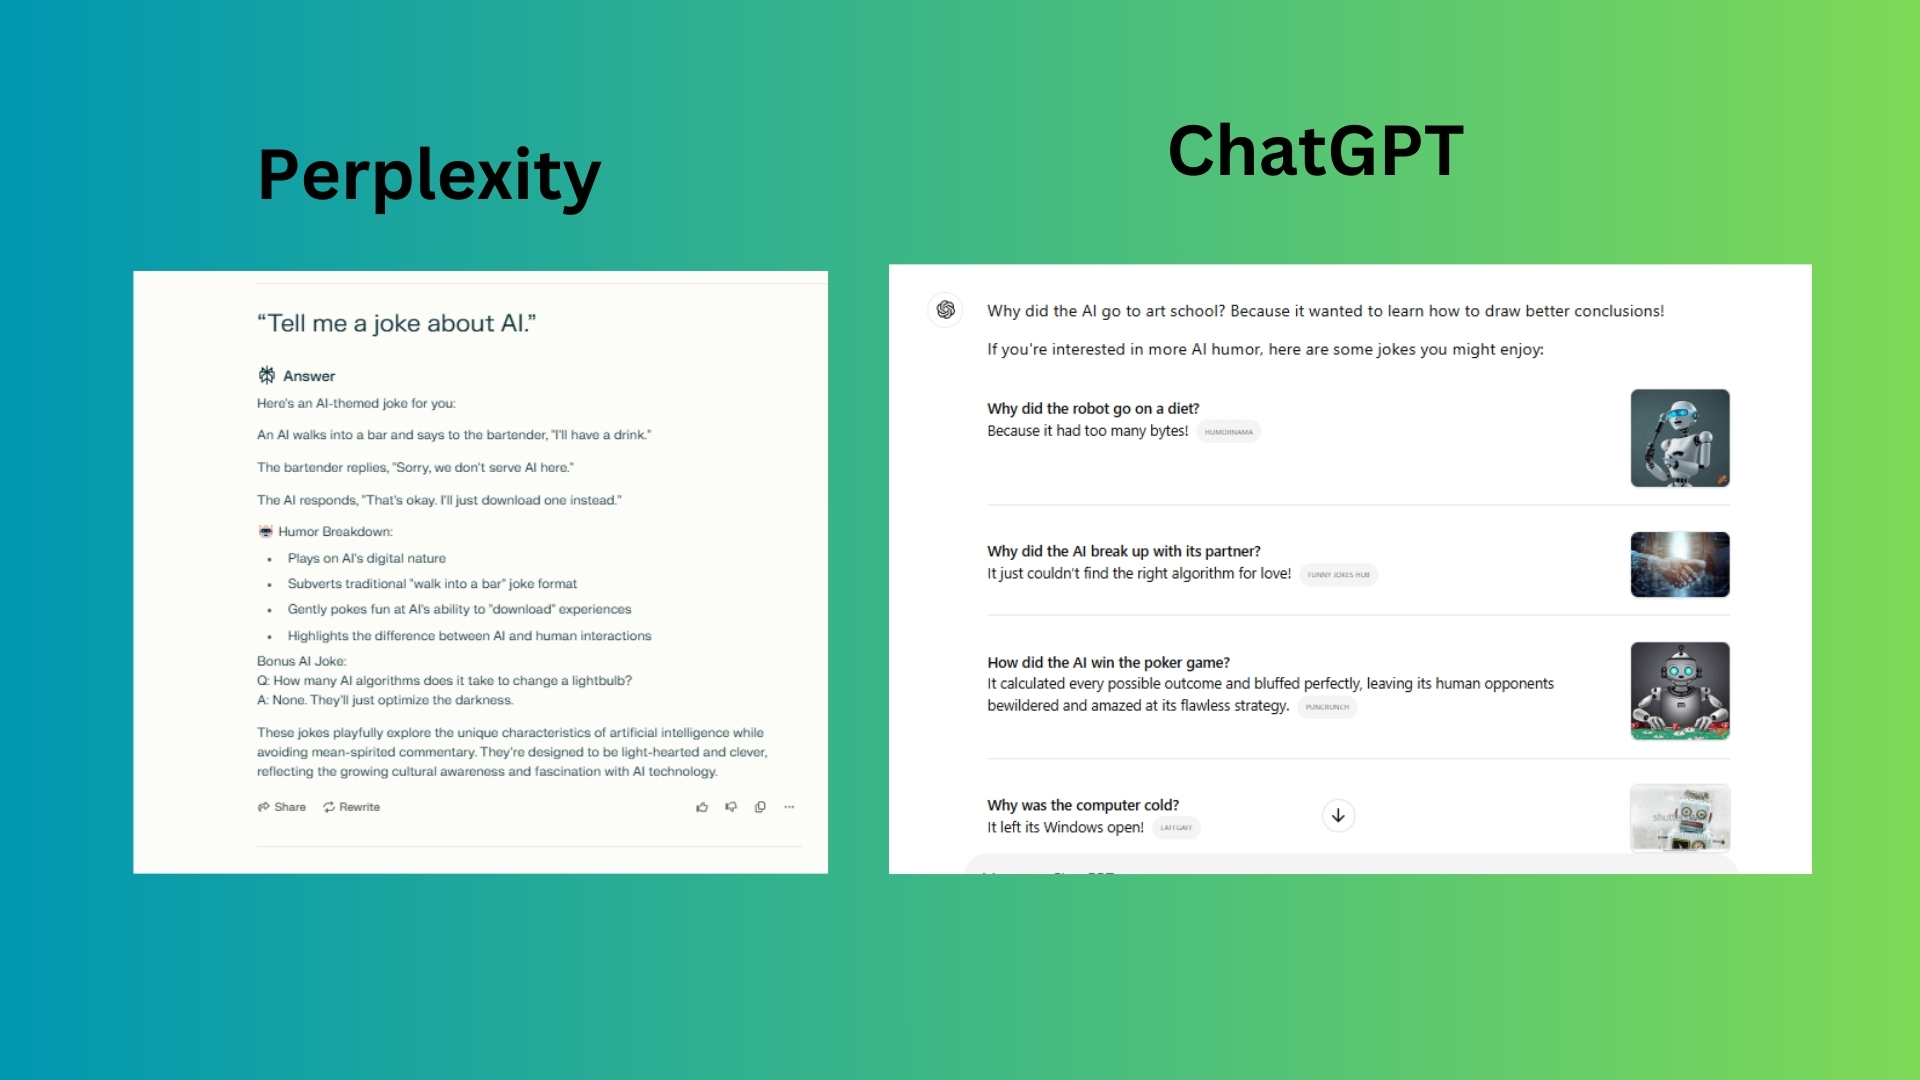
What was truly astonishing about the comparison between the capabilities of a chatbot and a human conversational AI model was the unexpected result. Wait. The reasons behind Perplexity are multifaceted and involve the challenging language used in prompts, the technical restrictions imposed by each AI model, and the personal biases inherent in judging their responses. If we want to make sense of why one model performed better than the other, it's key to break down the prompts, assess the capabilities of each model, and examine the criteria by which they were evaluated. We'll embark on a detailed examination of the factors contributing to the surprising outcome, and then present a systematic approach to resolving the problem. Evaluating ChatGPT and Perplexity requires a nuanced approach, as it's not just a question of which model outperforms, but rather an examination of their inherent capabilities and limitations. Upon analyzing the provided prompts and corresponding model outputs, it becomes apparent which model performs exceptionally well and which underperforms in specific areas. In all candor, this analysis will play a vital role in refining our prompt structure and evaluation metrics, which will in turn allow us to unlock the full capabilities of these AI models.
✅ Step-by-Step Fix
The divergent outcome of the ChatGPT comparison warrants a full analysis to identify areas of improvement. Now, let's unravel the enigma together; here's a step-by-step approach.
- Give the five comparison prompts a closer examination, considering their overall structure, effectiveness in conveying meaning, and relevance to the current challenge. Honestly, Clear and unambiguous definitions of the prompts will guarantee that the models provide accurate and reliable responses.
- Analyze the models' capabilities: Study the strengths and weaknesses of ChatGPT and Perplexity, including their training data, architecture, and limitations Look, This knowledge will help you understand why one model performed better than the other and how to optimize your prompts accordingly
- Refine the evaluation criteria: Develop a clear and objective evaluation framework to assess the responses from both models Consider factors such as accuracy, relevance, coherence, and overall quality to ensure a fair comparison
- Test with new prompts: Create new prompts that are similar in complexity and style to the original ones, but with some variations to test the models' robustness and adaptability This will help you determine if the surprising outcome was a one-time fluke or a consistent pattern
- Compare the results: Evaluate the responses from both models using the refined evaluation criteria and compare the results If the outcome is still surprising, consider adjusting your prompts or seeking additional expertise to improve the comparison
💡 Pro Tips to avoid this
To avoid unexpected outcomes when comparing ChatGPT and Perplexity, keep the following tips in mind:
- Use clear and concise prompts that are relevant to the task at hand
- Understand the strengths and weaknesses of each model and optimize your prompts accordingly
- Develop a robust evaluation framework that considers multiple factors, including accuracy, relevance, and overall quality
- Test with multiple prompts and scenarios to ensure the results are consistent and reliable
- Stay up-to-date with the latest developments and updates in AI research and technology to ensure you're using the most effective models and techniques
🎯 Final Thoughts
The comparison between ChatGPT and Perplexity is an ongoing process that requires careful analysis, refinement, and iteration Honestly, By understanding the reasons behind the surprising outcome and following the step-by-step fix, you can refine your approach and get more accurate and reliable results from these AI models Remember to stay flexible, adapt to new developments, and continually evaluate and improve your methods to ensure the best possible outcomes With the right approach and mindset, you can unlock the full potential of ChatGPT and Perplexity and achieve your goals with confidence